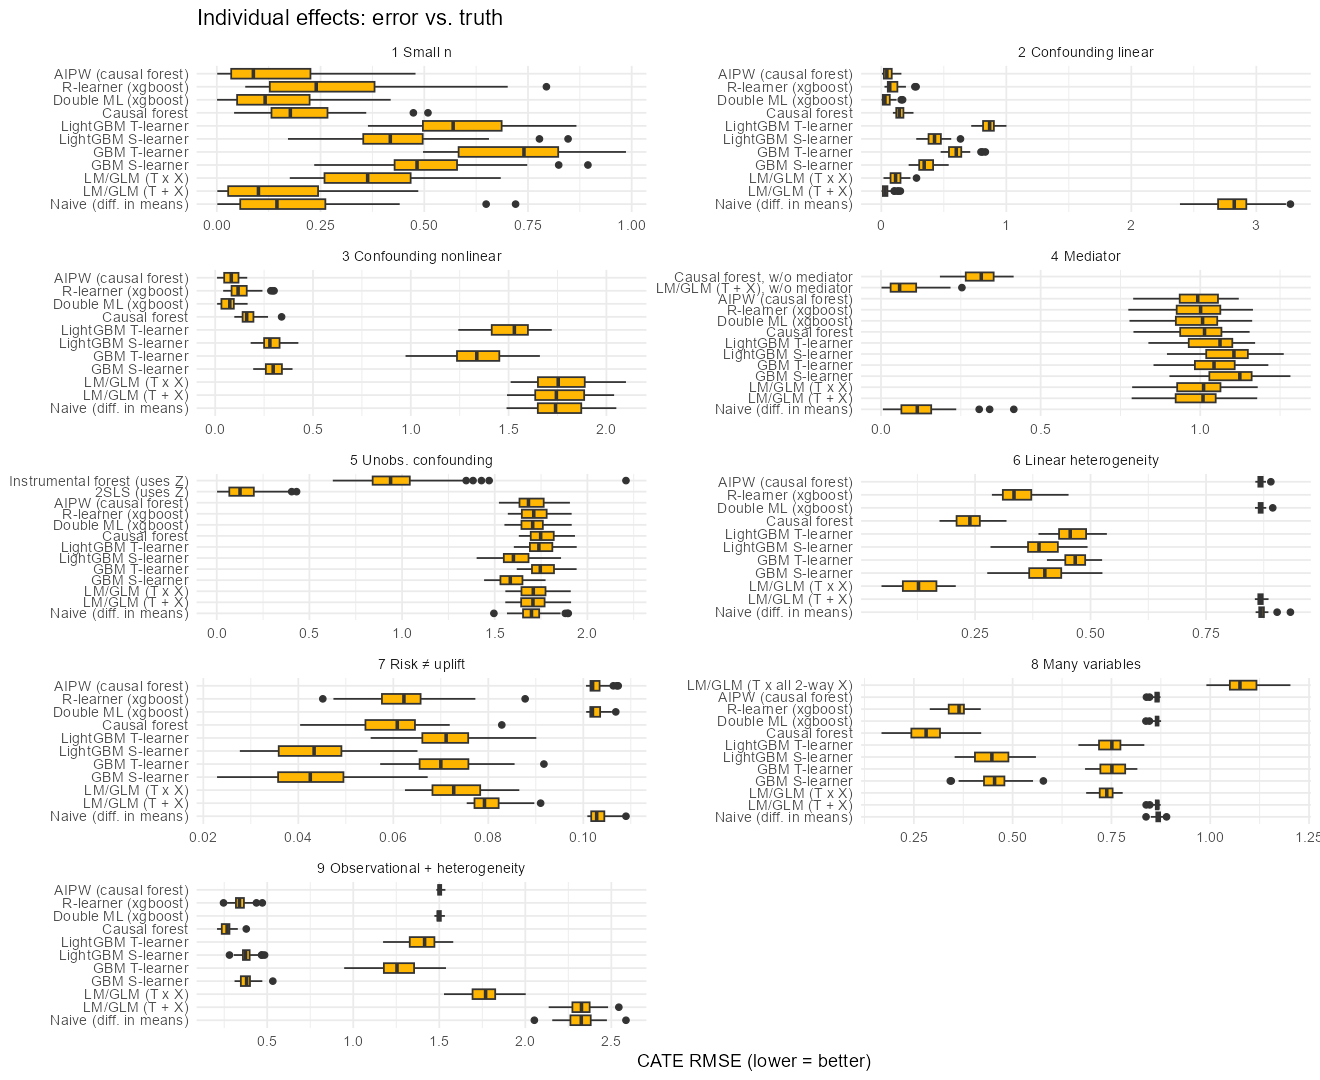
A simulation study with nine toy cases and a known true effect: when do causal forests, Double ML, AIPW and meta-learners beat plain LM, GLM and GBM, and how can you tell without knowing the truth?